Contexual Document Searching

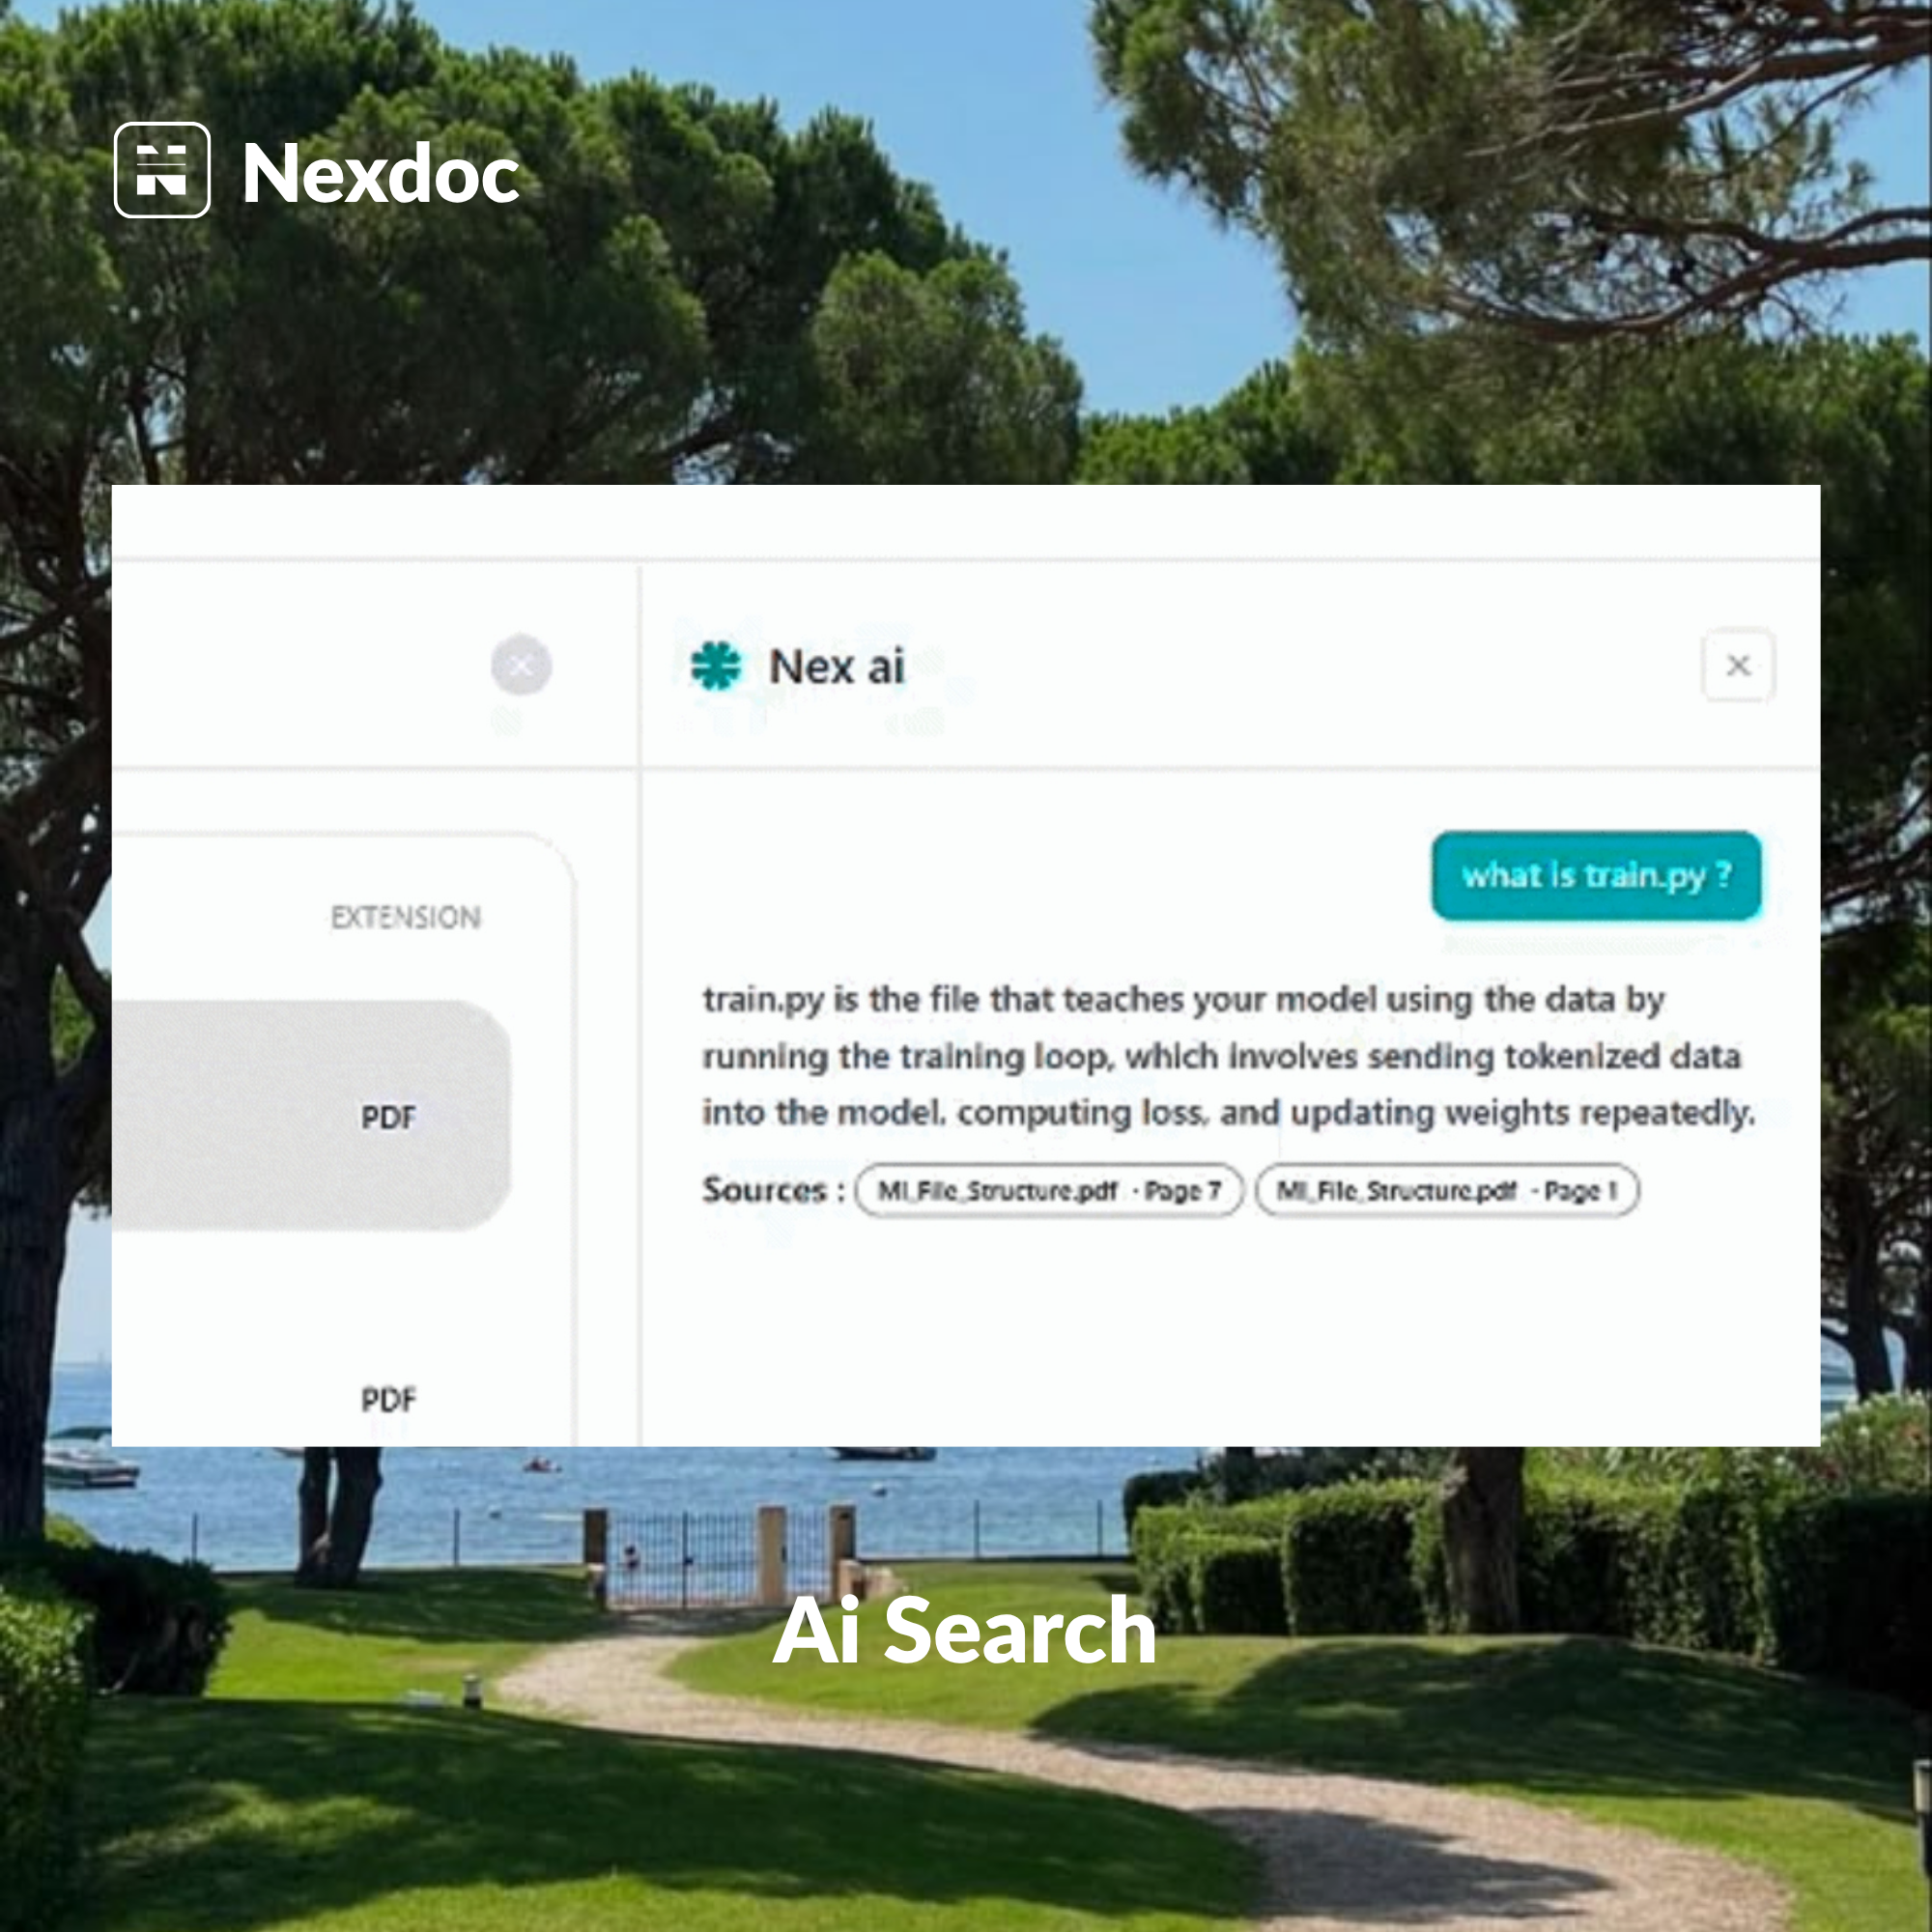
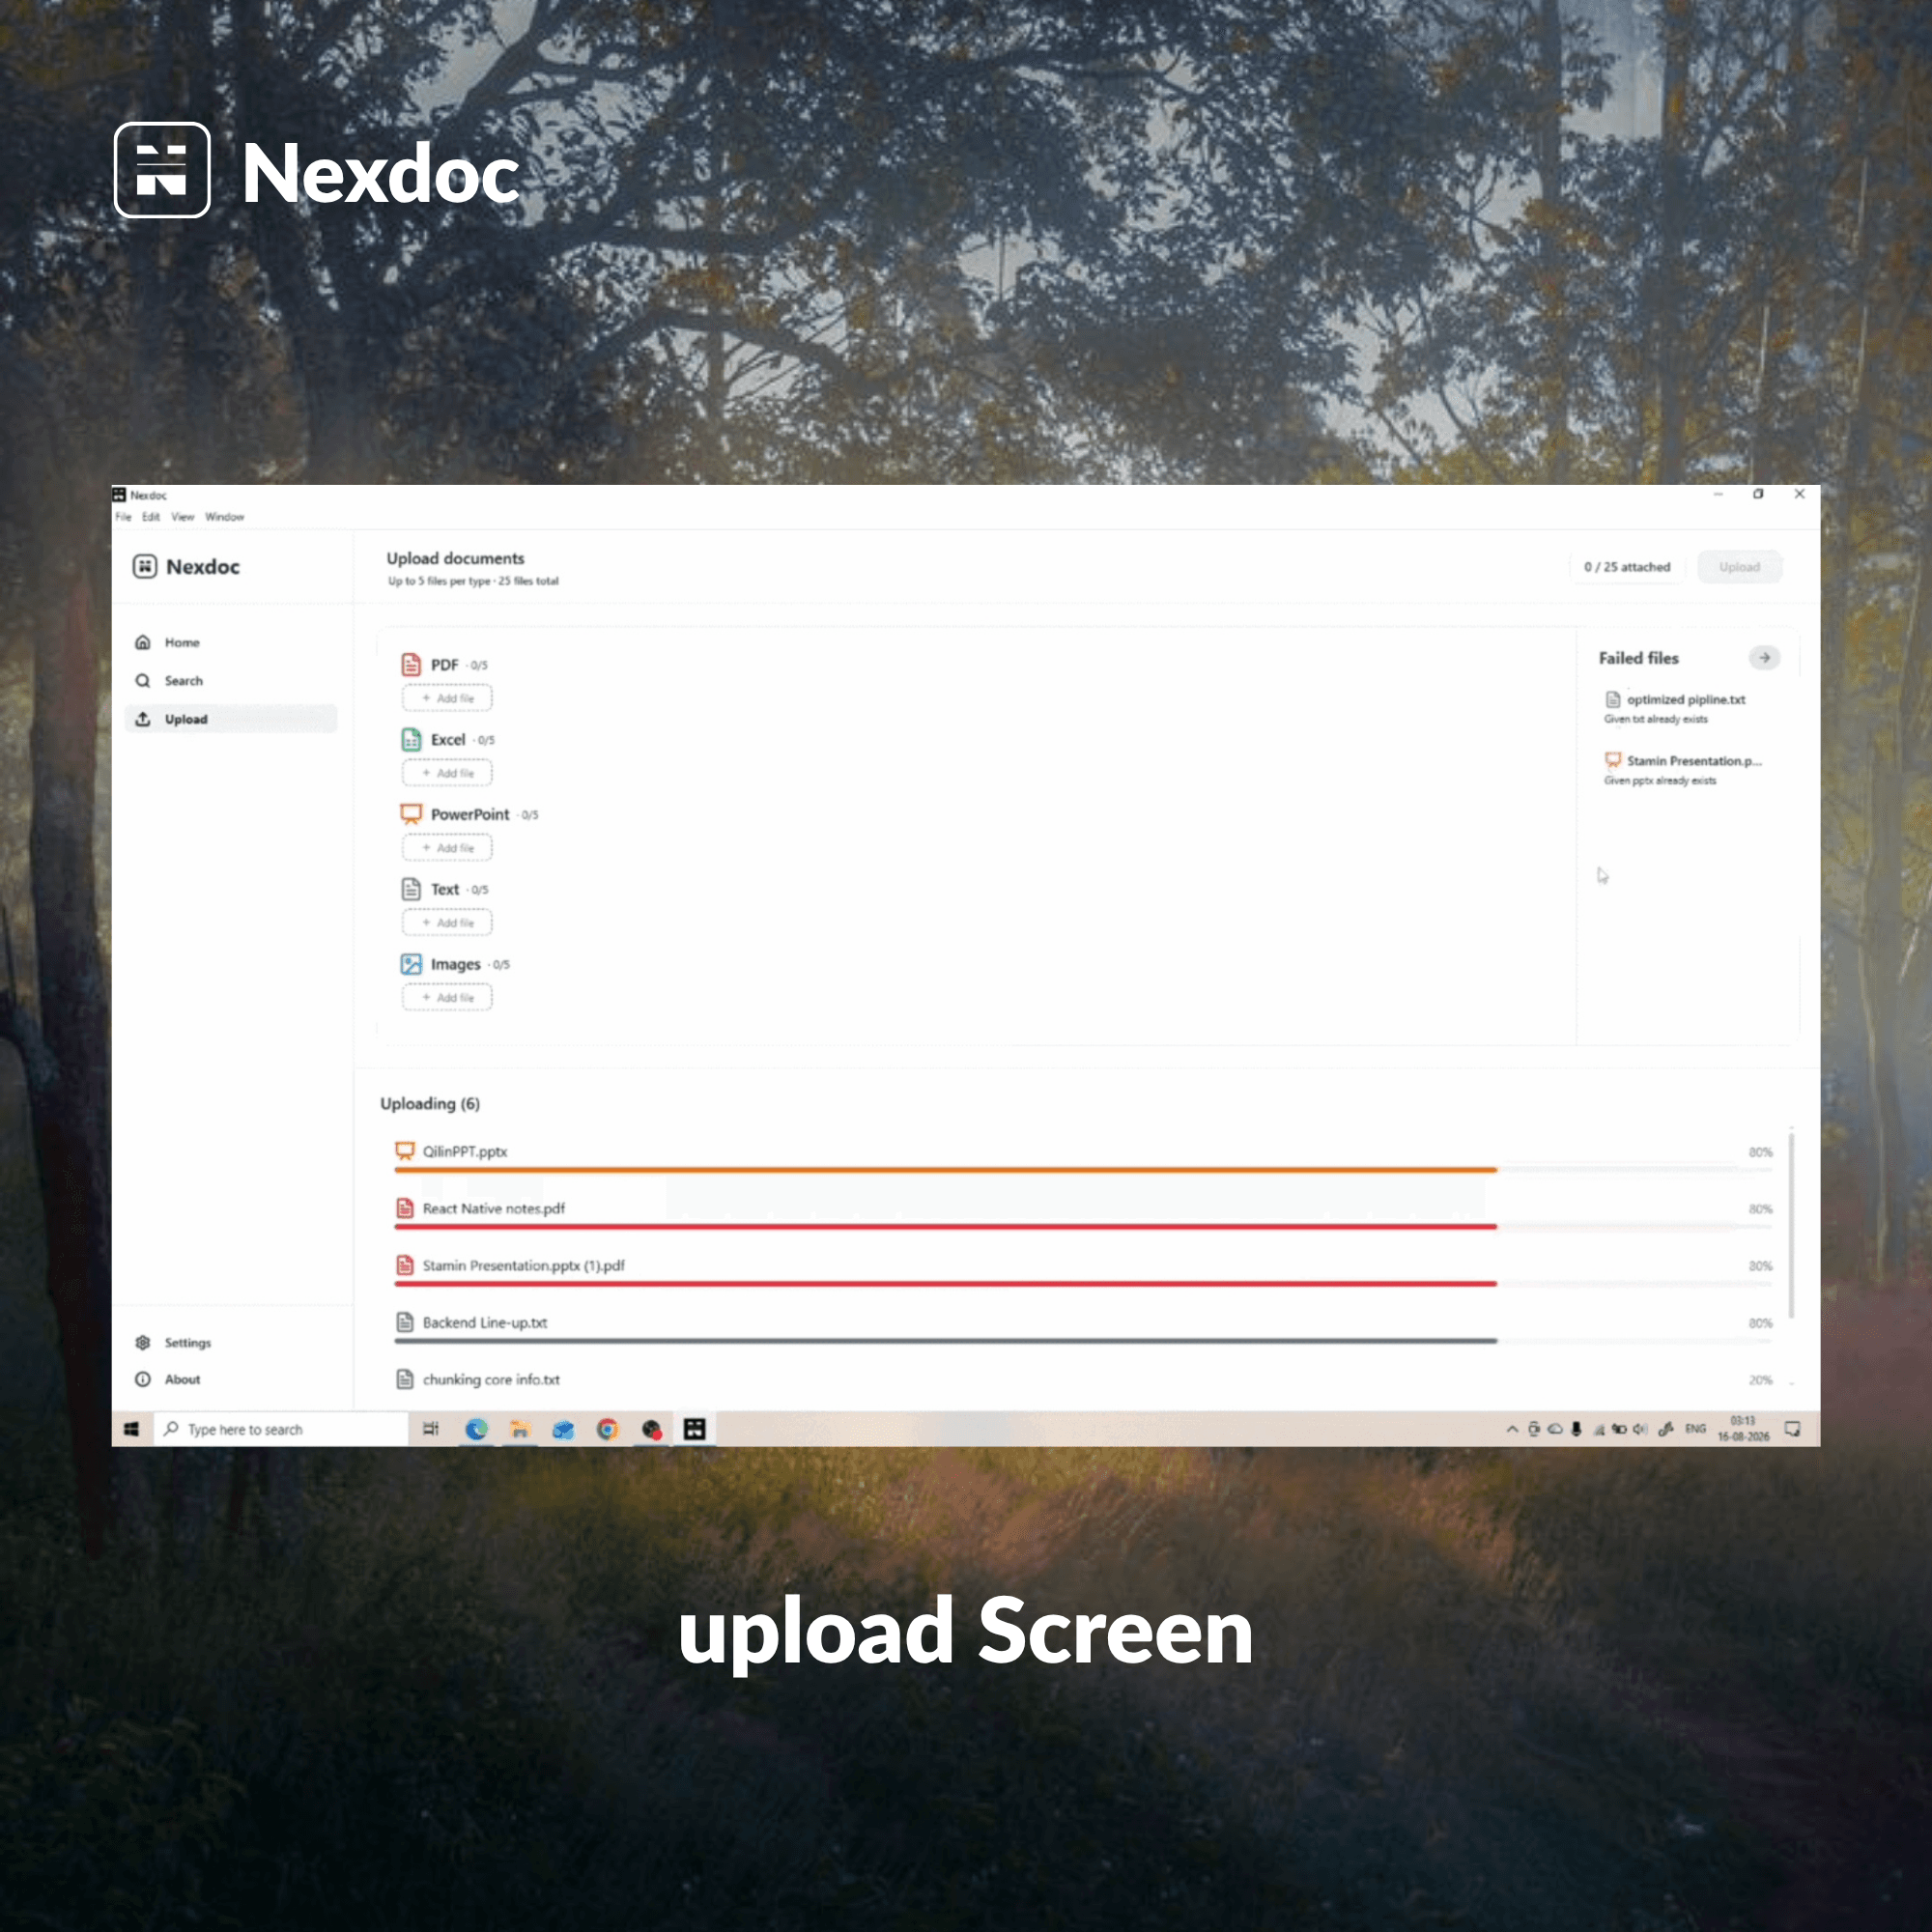
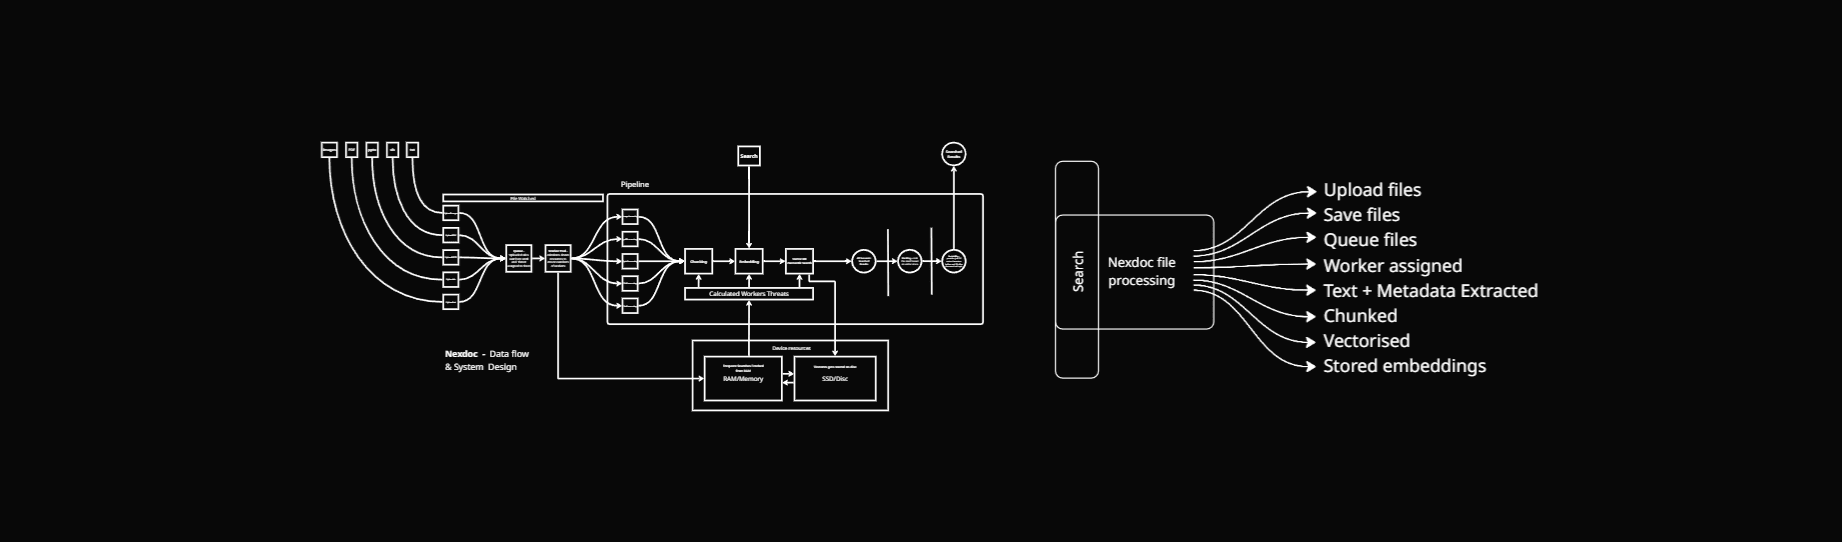
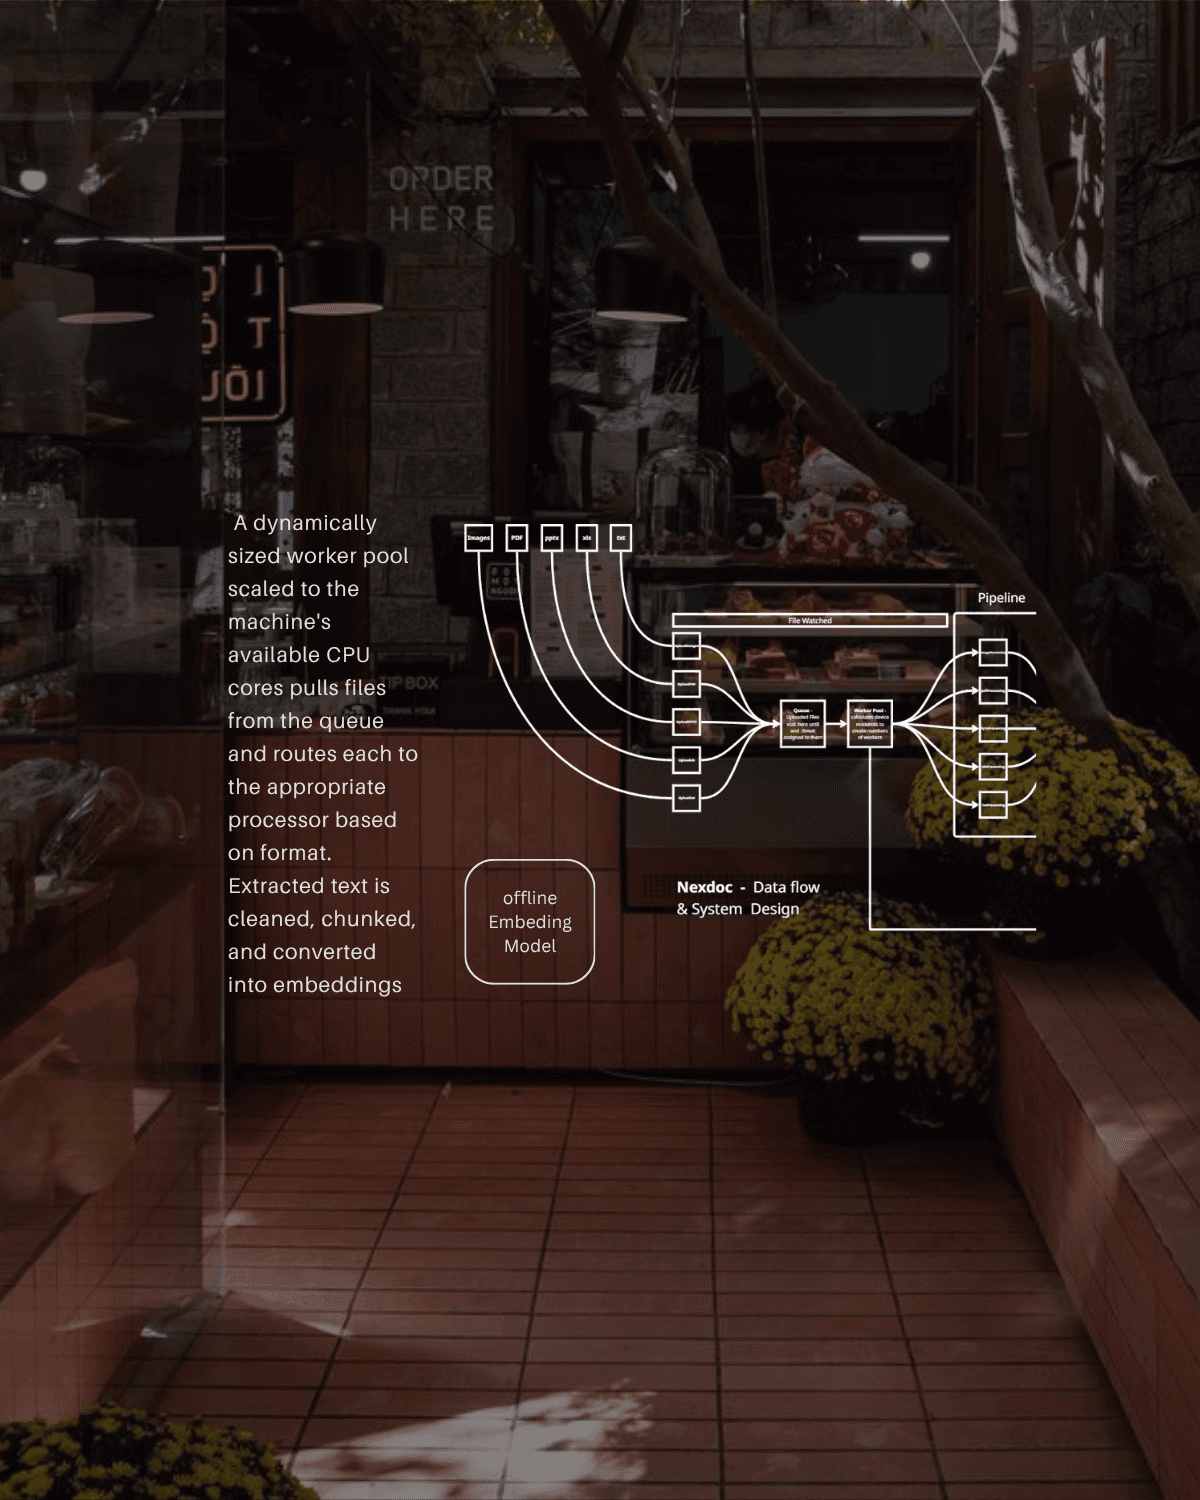
When a document is uploaded, it's stored locally and picked up by a Watchdog file watcher, which pushes it onto a processing queue. A dynamically sized worker pool scaled to the machine's available CPU cores pulls files from the queue and routes each to the appropriate processor based on format. Extracted text is cleaned, chunked, and converted into embeddings via a local Sentence Transformer model, then persisted in LanceDB alongside document metadata. At query time, the same embedding model encodes the user's search, retrieves candidates via vector similarity, filters and ranks them, and returns either raw ranked results (offline mode) or a synthesized, source-cited answer via the Gemini API (AI mode).
Nexdoc follows a layered Controllers → Services → Features → Repositories architecture on FastAPI, keeping API handling, business logic, and persistence cleanly separated. The Python backend is packaged using PyInstaller and bundled as a local sidecar process inside an Electron desktop frontend, so the entire application UI, backend, and vector database runs on the user's machine with no external server deployment required.